TECHNOLOGY / TENANT FAIRNESS
Every Connection Gets a Fair Turn. So Why Does One Tenant Get 80%?
Imagine an office with one coffee machine and two departments.
Department A sends one person.
Department B sends four.
Each person gets one equal-sized cup per round. A gets about 20% of the coffee; B gets 80%.
A asks:
“Weren’t the two departments supposed to share fairly?”
The reply:
“Everyone in the queue gets the same opportunity.”
Both sides are talking about fairness. They just have different units in mind.
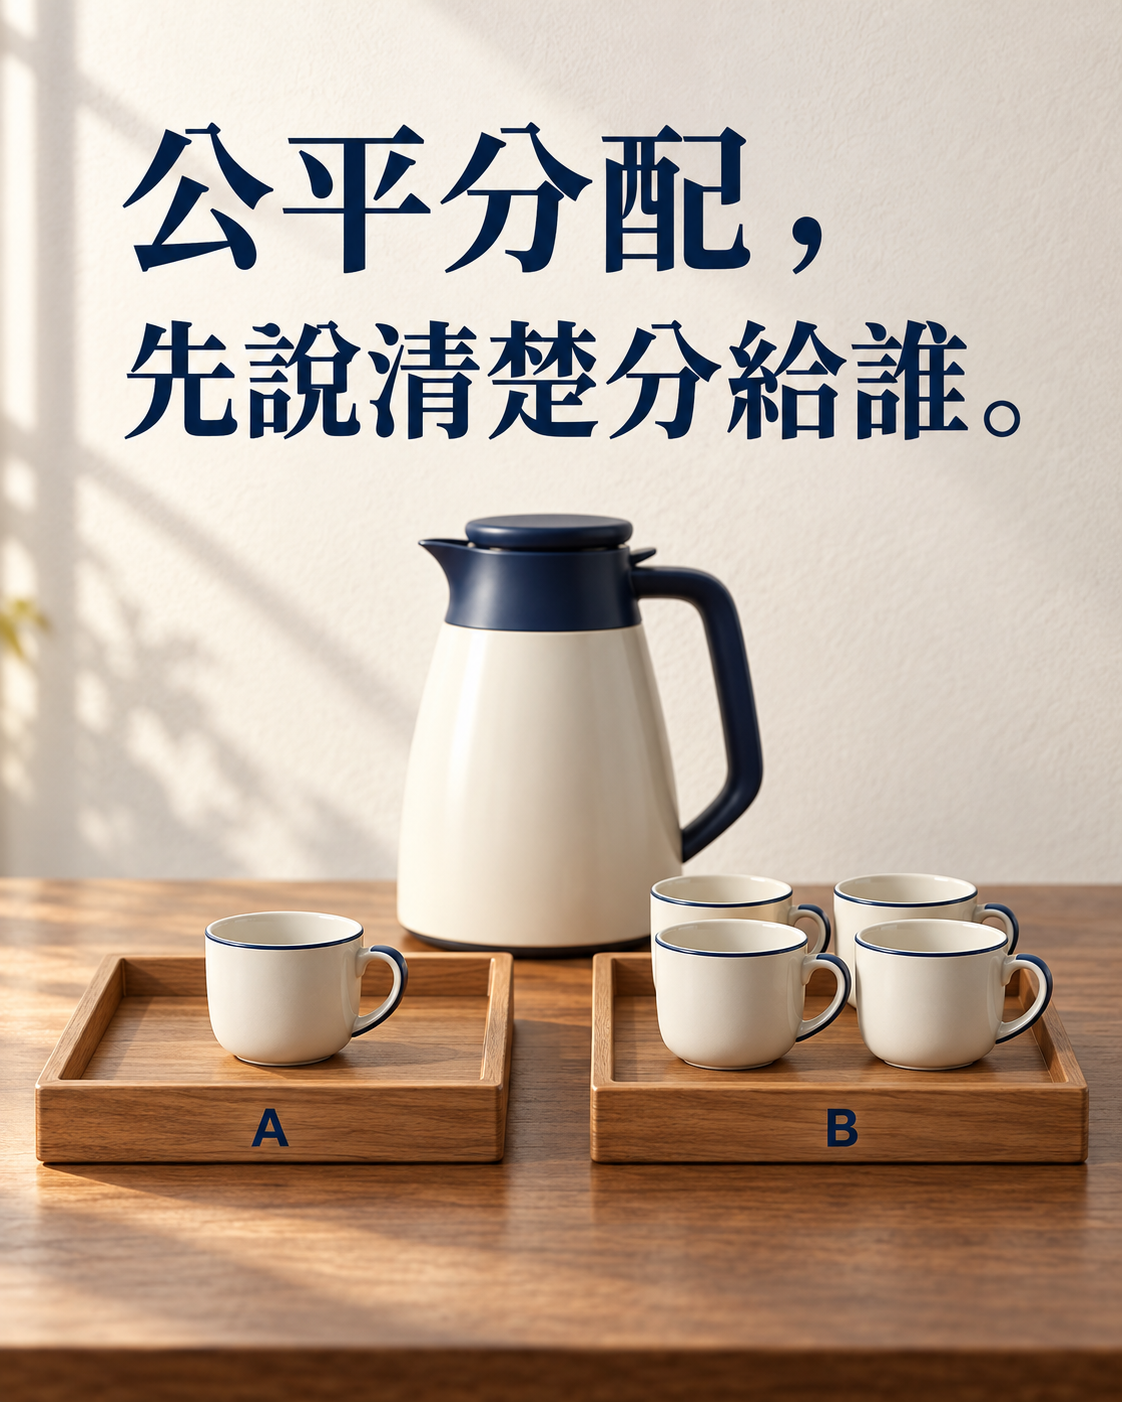
Connections and tenants are different units
I recently built tiny-fair-proxy, an experimental TCP relay in Rust with bounded payload buffers, backpressure, and tenant-weighted byte scheduling.
The question I wanted to explore was simple:
Should a tenant get more bandwidth just because it opens more connections?
A connection and a tenant are different units of allocation.
Give every connection a turn, and a tenant with more connections can receive a larger share.
The scheduler may be working exactly as designed.
It is delivering a different kind of fairness.
Shares within a common observation window
In this controlled experiment, tenant A had one connection and tenant B had four. Each connection transferred 512 KiB.
I tested upload and download with A:B weights of 1:1 and 1:3, comparing two scheduling modes across three randomized paired blocks: 24 trials in total.
The environment was native macOS ARM64 loopback, with a shared 512 KiB/s rate cap applied independently in each direction.
Start with equal weights.
During the common receiver observation window, 0.4–1.4 seconds after the common workload start, A’s median share of received bytes was approximately:
Connection round robin: 20%.
Tenant-weighted scheduling: 50%.
Those are shares within that window, not shares of the entire workload.
All five connections had the same amount to send. Once every transfer finished, A still accounted for 20% of the total payload bytes.
Overall throughput was broadly similar between modes, measured from the common workload start until the last transfer completed, including the final tails.
The bandwidth had not increased.
What changed was who received it while the tenants competed for it.
B still represented one tenant, even with four connections.
Under the tenant-based policy, opening four connections does not automatically upgrade its bandwidth allowance.
But fair does not always mean equal.
With equal weights, the target is roughly half each when both tenants have data to send and writable destinations. Different weights change that target proportion.
An idle or non-writable tenant does not bank unused service credit. Other tenants can use the available bandwidth.
If you skip coffee today, the machine does not need the day off.
Which tenant does this connection belong to?
There is another question before any of those ratios matter:
How does the proxy know which tenant a connection belongs to?
This implementation maps separate listeners to designated tenants and fixed backends.
That is a classification mechanism for a trusted local environment, not authentication.
It does not stop someone from using multiple identities or impersonating another tenant.
If the classification cannot be trusted, a tidy scheduling ratio cannot protect the allocation we intended.
Buffers, backpressure, and a shutdown deadline
Allocation is only part of the job.
When a payload buffer fills, the proxy must stop reading and apply backpressure. A slow receiver must not cause unbounded payload buffering.
When EOF arrives in one direction, the proxy drains that direction’s buffer before shutting down the destination socket’s write side. Reverse traffic can continue independently.
New connections beyond the configured limit must be rejected explicitly.
On shutdown, the proxy stops accepting new connections and gives existing ones a bounded opportunity to drain.
The deadline can still interrupt transfers. It is not a promise that every byte will be delivered.
“Graceful shutdown” cannot mean:
“Take your time. I’ll be here forever.”
A graceful shutdown still needs a deadline.
Measurement boundaries and resource commitments
The measurement boundaries matter.
This was a deliberately rate-limited loopback bottleneck, not a measurement of real-world Internet performance or a speed contest against NGINX, Envoy, or HAProxy.
Receiver shares over one observation window do not guarantee exact ratios at every instant. Byte scheduling is not an application-request latency guarantee, either.
Memory measurements sampled the proxy process’s RSS. They excluded peer processes and kernel socket buffers, and sampling can miss short-lived peaks.
Bounded payload buffers do not establish a bound on the entire system’s memory cost.
For me, the useful result is that “fairness” becomes a set of questions we can inspect:
Are we allocating per connection, per tenant, or per request?
Can we trust the tenant classification?
Who chooses the weights, and when should they change?
Can others use capacity that one tenant leaves idle?
Under overload, do rejection and waiting behavior still meet the service requirements?
A scheduler cannot make those decisions for us.
It implements the rules. We need to decide whether those rules match the resource commitments we intend to make.
Per-connection allocation is not inherently wrong.
Per-tenant allocation does not solve every fairness problem.
Define the unit, the weights, and the identity boundary first. Then we can judge the result.
Otherwise, the system may follow every rule—and still distribute resources in a way that does not match the promise we thought we made.